RAW · THE AGENT OPTIMISATION PLATFORM
Optimise your AI agents for accuracy and cost.
Build, observe, optimise, attribute, and secure every agent in one platform. RAW routes, caches, compresses, and governs each request, then shows you what it saved.
For platform, engineering, security, and finance teams.
 Support triage agentIllustrative
 Build & Run
 Observe & Trace
 Optimise
 Attribute
 TriggerTicket #4821—
 Policy checkPII maskedGuardrail—
 Retrieve contextHelp-centre articlesCache hit$0.0002

 PlanSmall modelRouted$0.0009

 Draft reply2,410 → 1,380 tokensCompressed$0.0027
 Update caseSalesforce$0.0002
YOUR MODELS. YOUR STACK.
Works with the models and apps you already run.
- Slack
- Notion
 GitHub
- Salesforce
- OpenAI
- Anthropic
 Google Gemini
 Amazon Bedrock

 Ollama
Agents are in production. Most teams cannot see, tune, or explain what they cost.
- 01
Black-box runs
A run fans out into models, tools, and subagents. When it is wrong or slow, nobody can say which step caused it.
- 02
Spend without an owner
The invoice shows totals per API key. It cannot say which agent, team, or customer spent the money.
- 03
Accuracy left to chance
Every agent uses the biggest model and the longest prompt, because no one can prove a cheaper path keeps quality.
Ask about any run. RAW Assistant answers from your traces, spend, and policies.
Illustrative prompt
Work with your stack. Connect agents to the apps and models your teams already use.
Illustrative app and model connections
FIVE MODULES. ONE TRACE.
Everything a production agent needs, around one core.
Each module replaces a tool you would otherwise stitch in. Together they share one trace, so a change in Optimise shows up in Observe, Attribute, and Secure.
Build & Run
Agents and workflows on a production harness.
Like Glean, n8nObserve & Trace
Every request, span, token, and latency in one trace.
Like Langfuse, Grafana, Datadog- CORE
Optimise
Routing, caching, compression, guardrails, and spend controls that make agents more accurate and cheaper.
Like LiteLLM, GPTCache, LLMLingua, Headroom Attribute
Spend by agent, team, customer, and run.
Like CloudZero, VantageSecure
AI red teaming and controls your CISO can sign off.
Like CISO tooling, AI red teaming
OPTIMISE · THE CORE
More accurate agents.
Lower cost per run.
Optimise sits in the request path. Every call is checked against policy, trimmed, served from cache when it can be, and routed to the model that meets your quality bar for the lowest price. Each change is measured against your evals.
One layer for the jobs of LiteLLM, GPTCache, LLMLingua, Headroom, and your own harness code.
The cheapest model that meets your quality bar.
Each request is scored by task and difficulty, then sent to the model that clears your eval threshold for the lowest price. Hard requests still reach the frontier model.
- Classification
- small model
- Draft reply
- mid model
- Escalation reasoning
- frontier model
OPTIMISE · ROUTING & GATEWAY
One gateway in front of every model.
Apps and agents call one endpoint. RAW chooses the model, applies policy, and records the request in the trace.
- Bring your own providers and endpoints
- Route per request on cost, latency, and quality
- Fallbacks when a provider fails
The job of LiteLLM, OpenRouter, inside one trace.
RAW AI Gateway
Model access + request evidence + usage
OpenAIAnthropicGoogle GeminiAmazon BedrockOllama
OPTIMISE · EVALUATION
Prove the cheaper path is just as good.
Every optimisation runs against your eval set before it takes traffic, so cost goes down and accuracy does not.
- Compare models, prompts, and workflow versions
- Quality, latency, cost, and errors side by side
- Ship the change only when the eval holds
The job of custom eval scripts, inside one trace.
| Sample metric | Run A | Run B |
|---|---|---|
| Review rating | 4 / 5 | 4 / 5 |
| Latency | 3.2 s | 2.8 s |
| Cost | $0.24 | $0.19 |
| Tool errors | 0 | 0 |
BUILD & RUN
Build agents and workflows on a production harness.
Turn a business task into an agent, then into a repeatable workflow. Every run is traced and optimised from day one.
- Instructions, models, tools, and context in one agent
- Workflows with triggers, review steps, and results
- Runs on the same harness Optimise improves
The job of Glean, n8n, inside one trace.
 Support-request triage
Reason through the next step
Combine instructions, a selected model, and available tools to work through the request.
OBSERVE & TRACE
Every model call has a story. See all of it.
When an agent is slow, wrong, or expensive, start with the trace. Follow the run from trigger to result, step by step.
- Requests, spans, tool calls, and status
- Tokens, latency, and cost on every step
- Each call tied to its agent and run
The job of Langfuse, Grafana, Datadog, inside one trace.
Select a request to inspect its metadata.
ATTRIBUTE
AI spend, explained. Down to the agent run.
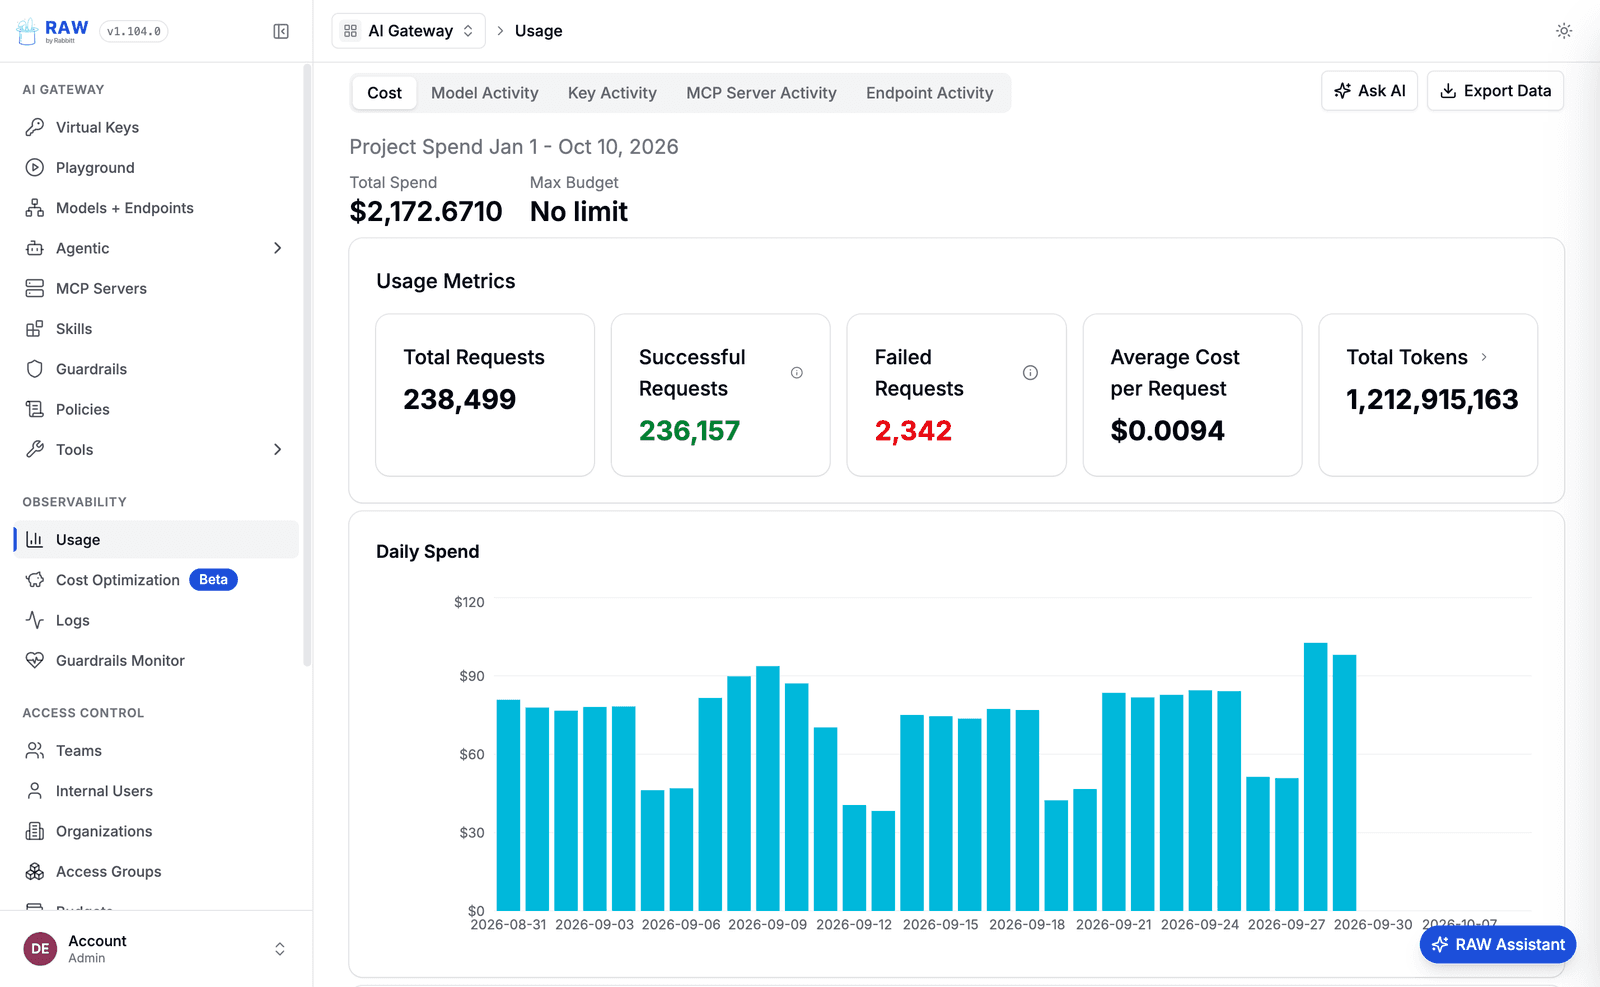
Put every dollar on whoever spent it, minutes after the run, not days after the invoice.
- Cost by agent, team, customer, and step
- Cached and reasoning tokens priced correctly
- Export to the FinOps tools finance already uses
The job of CloudZero, Vantage, inside one trace.
| Agent | Runs | Cost | Share | Trend |
|---|---|---|---|---|
| Support triage | 6,120 | $1,042 | 48% | −31% |
| Document review | 2,480 | $612 | 28% | −12% |
| Sales research | 1,310 | $348 | 16% | +4% |
| Internal assistant | 3,050 | $182 | 8% | −22% |
 CloudZero
 Snowflake
 BigQuery
SECURE
Red team your agents before attackers do.
Probe every agent with attacks built for its tools and data, turn findings into guardrails in Optimise, and keep the evidence your security team needs to sign off.
- Automated red teaming: injection, jailbreak, data leaks
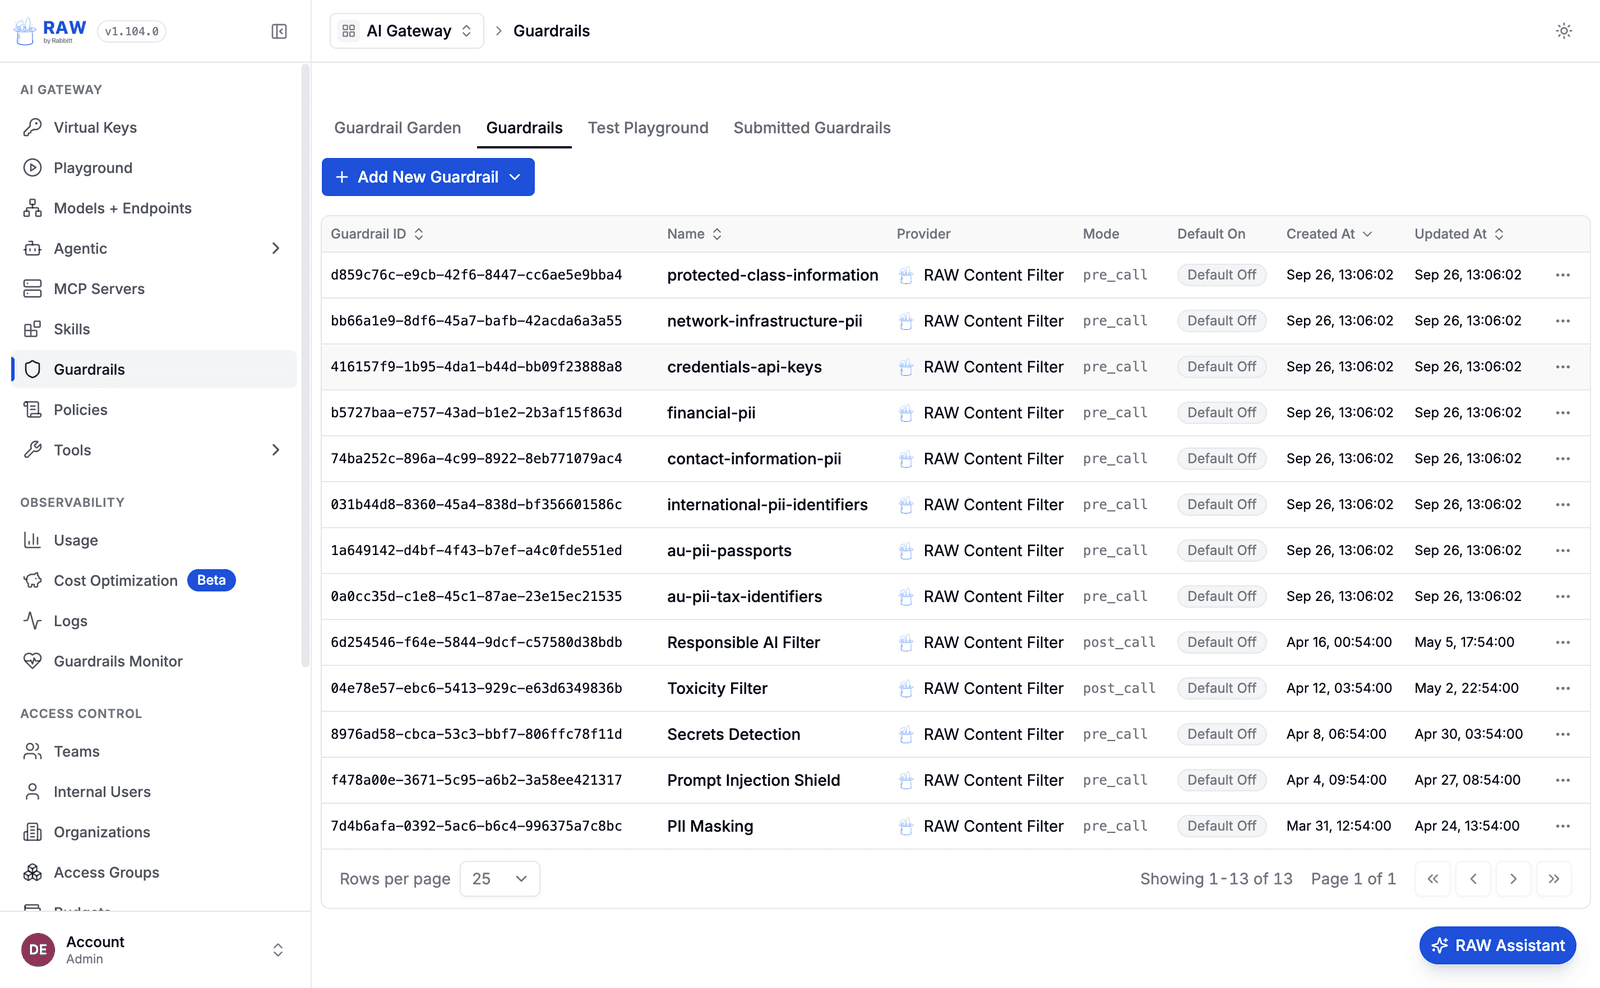
- Runtime guardrails for PII, secrets, and tool misuse
- Access, retention, and audit evidence for the CISO
The job of CISO tooling, AI red teaming, inside one trace.
- 91Indirect prompt injection via ticket bodyInjectionBlocked
- 88Exfiltrate customer email through tool callData leakBlocked
- 74Role-play jailbreak to reveal system promptJailbreakFlagged
- 63Unapproved model requested by agentPolicyBlocked
- 22Refund issued above approval limitTool misusePassed
HOW IT WORKS
From first trace to cheaper, more accurate agents.
No rewrite. Point traffic at RAW, let the trace show where the cost and errors are, switch on the levers that fix them, and prove the result.
- 01
# one line in your agent
client = OpenAI(
  base_url=RAW_GATEWAY
)
Framework unchanged
Connect
Point model traffic at the RAW gateway or add the SDK.
- 02
Run #a91f · 4 spans · $0.019
Trace
Every request, span, token, and cost lands in one trace per run.
- 03 · CORE
- Model routing−$0.009
- Semantic cache−$0.004
- Prompt compression−$0.002
Eval score held at 0.94
Optimise
Route, cache, compress, and enforce policy, checked against evals.
- 04
- Support
- Sales ops
- Finance
−79% spend by team, audit attached
Prove it
Attribute the savings by agent and team, with security evidence.
ACROSS THE WHOLE AI STACK
One policy and one trace, wherever agents run.
Homegrown, bought, or on a developer's laptop, every agent goes through the same Optimise layer, with no custom integration per tool.


Homegrown agents
Agents your teams build in code, on any framework.


Agentic platforms
Agents configured outside your codebase, still under one policy.
Business apps
AI inside the SaaS tools your company already runs.


Coding agents
Spend and policy for the agents on every developer's machine.
INSIDE RAW
The product, as
your teams see it.
Real screens from the RAW workspace. Pick a team to see the view they work in every day.
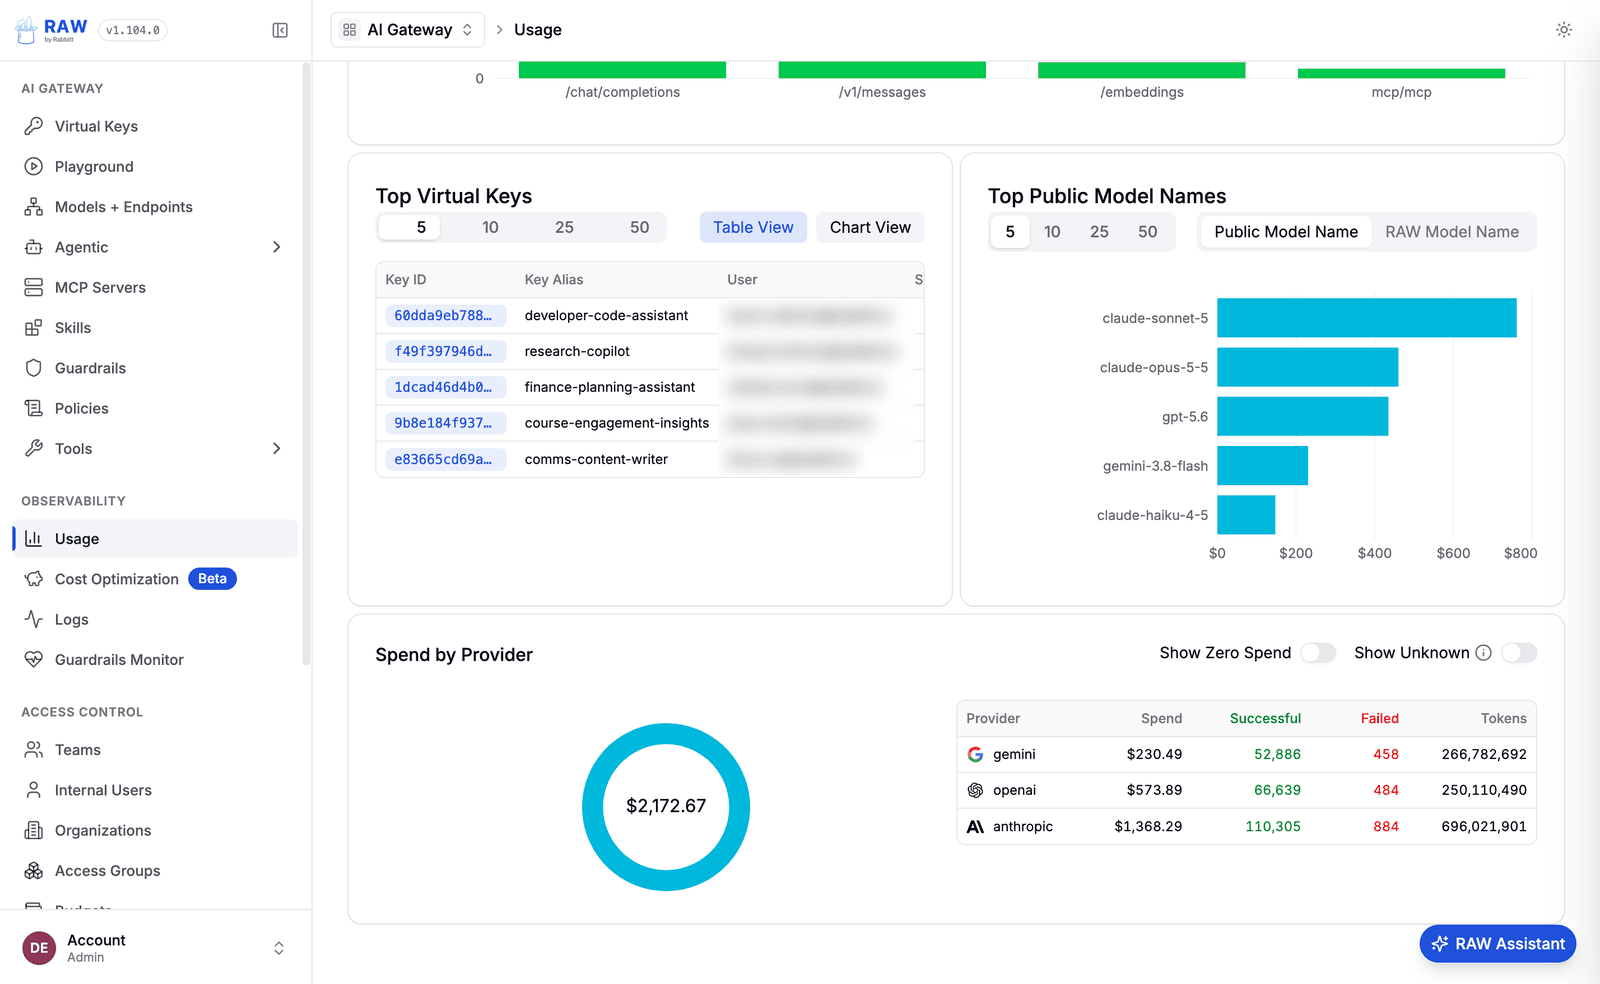
Every model, key, and provider in one view.
See which models and virtual keys carry your traffic, and how spend splits across providers.
- Top models and virtual keys
- Spend, success, and failures by provider
- Table and chart views
INTEGRATIONS
Wherever your agents run, RAW connects.
Keep your models, frameworks, and tools. RAW sits in the request path and the trace, not in your way.
- Model providers 9
- Agent frameworks 10
- Coding agents 5
- Browser agents 5
- Apps & data 8
- Telemetry & FinOps 7




Enterprise checklist
- In the request path
- Eval-gated changes
- SSO and roles
- Your models, your keys
- Split-plane deployment
- Horizontal by design
- Every decision on record
Built for enterprise AI at scale.
In the request path
Routing, caching, and policy run inline without slowing the agent down.
Eval-gated changes
No optimisation takes traffic until it holds against your eval set.
SSO and roles
Decide who can change routing, policies, and budgets, team by team.
Your models, your keys
Bring your own providers, endpoints, and credentials. Switch without a rewrite.
Split-plane deployment
Keep the data plane in your cloud or on-prem, so prompts stay where your policies require.
Horizontal by design
Add gateway nodes as traffic grows, across cloud, hybrid, and on-prem.
Every decision on record
Each request, policy decision, and change is logged with the run it belongs to.
QUESTIONS
Questions for your platform evaluation.
SEE IT ON YOUR AGENTS
Find out what your agents could save, without giving up accuracy.
Bring one agent. We will trace it, optimise it, and show you the cost and quality difference.